Confidence Threshold Calibration for Document Extraction Queues
Confidence scores don't predict accuracy unless you measure them against ground truth first.
A confidence score on an extracted field looks like a probability. Most teams treat it that way: the number gets read as a direct measure of correctness, and the routing logic gets built on that assumption. Nothing in how these scores are generated guarantees that relationship holds. The number a model reports and the actual rate at which that field is correct are two separate things, and they only line up if someone has gone and measured them against each other.
That gap is most visible in how LLMs score their own extractions. They overscore, clustering their confidence at 0.9 and above even on fields that are ambiguous or flat-out wrong. A model can be confidently wrong, reporting high certainty on an output that doesn't match the document it came from. It is the normal behavior of the score, and any queue that auto-accepts above a threshold without checking that behavior first is accepting errors it believes it has screened out.
This matters because the accept/review decision in a document extraction queue is built entirely on trusting that number. If the score doesn't track real accuracy, every downstream decision inherits the error: fields get auto-approved that shouldn't be, and the audit trail shows a high-confidence pass instead of a flagged exception. The fix is treating the score as an unverified claim until it's been checked against ground truth, field by field.
How pipeline architecture compounds the calibration problem
Document extraction doesn't happen in one step. A production pipeline runs through ingestion, preprocessing, OCR, layout analysis, extraction, and validation, and each of those stages adds its own error on top of the last. The confidence score that gets attached to the final extracted field carries none of this history. It reflects the extraction model's read on its own output rather than the compounded damage done upstream.
OCR quality drives most of that damage. A clean digital PDF can hit near-perfect character accuracy, but a photographed, crumpled receipt falls far short. You often gain more by improving preprocessing and scan quality than by tuning a threshold. If a team spends weeks tightening its confidence cutoff while feeding the model badly scanned images, it is optimizing the wrong layer of the stack.
Infrastructure can introduce a failure class that has nothing to do with model quality and that confidence scores are structurally blind to. If a message queue's visibility timeout is set shorter than actual processing time, a document in progress can get redelivered to a second worker while the first is still working on it, producing duplicate results. No confidence score catches this, because the mismatch is between how long processing takes and how long the queue is willing to wait before assuming the job failed.
Put together, these stages mean a team that calibrates its threshold only by looking at the extraction model's output, with clean test documents and no infrastructure noise, is calibrating against a distribution of inputs that production will not actually deliver.
The three mechanisms that make naive threshold-setting silently violate its own guarantee
The usual fix for an untrustworthy confidence score sounds reasonable: hold out a labeled set of documents, find the threshold where accepted fields stay under a target error rate, and deploy that threshold. On real documents, this procedure breaks in three distinct ways, and each one needs its own fix.
The first is document clustering. Fields pulled from the same document aren't independent of each other: they share the same scan quality, the same layout, the same model behavior on that particular page. Treating every field as its own independent data point overstates how much the calibration set actually knows, because a messy receipt gives you several correlated data points, not several independent ones. A held-out set of fields ends up behaving statistically like a much smaller, noisier set, so a threshold chosen from it carries far less certainty than its raw size suggests.
The second is leakage between fitting and calibrating. If the confidence score itself and the threshold applied to it are learned from the same fields, the threshold comes out looking better than it will perform live. This is a subtle trap: the team that builds its own scoring layer and tunes it on the same data it calibrates against has built a number that flatters its own test.
The third is tie-mass collapse. When a scoring model produces the same number for a large cluster of fields rather than a smooth spread of values, the grid of possible thresholds collapses, and the certified coverage the procedure promises can drop sharply and with little warning. A scoring function that isn't expressive enough to spread its outputs out is fragile in a way that's invisible until the distribution shifts.
These three failures are distinct and quantified mechanisms that must each be addressed independently, since fixing one doesn't fix the others. A team that separates its fitting data from its calibration data to kill leakage still has to deal with document clustering. A team that accounts for clustering still has to watch for tie-mass collapse if its score distribution bunches up. The honest response isn't a single better default threshold. Across the validity ladder, only the rigorous doc-iid PAC tier has an exchangeability assumption that matches real documents.
Requirements for Calibrated Confidence: Ground Truth, Field Granularity, and Document-Type Separation
Fixing a confidence score is a measurement exercise. It means checking a model's reported scores against actual outcomes and correcting the gap, not adjusting a setting somewhere in the pipeline.
Ground truth comes first, and nothing else works without it. A field reporting 0.85 confidence should be correct roughly 85% of the time; if the real rate on labeled data is closer to 70%, the threshold has to be set against that real number, not the model's claim. This requires an actual labeled set of production documents built for this purpose, not a clean benchmark dataset built for a different one. If you skip this step, every later decision rests on an unverified assumption.
Field type changes the picture substantially. Dates tend to cluster tightly in a high-confidence band because they follow a small number of predictable formats. Signatures scatter widely, because they look inconsistent and a model finds them hard to judge. Structured amounts, like totals or line items, tend to stay tight and reliable. If you apply a single threshold across every field type, it waves through types that are systematically overscored and rejects types that are systematically underscored, even when both are performing fine.
Document type matters just as much. A threshold tuned on clean invoices will approve too many bad fields on handwritten receipts and reject too many good fields on simple, well-formatted forms. One global cutoff produces false approvals in easy domains and false rejections in hard ones at the same time, so you need to set thresholds separately for each document type a pipeline actually handles.
Critical fields, like invoice number or total amount, need a fixed threshold rather than a ranking-based cutoff. A percentile-based rule, which approves whatever ranks highest within a batch, can wave through an entire bad batch if the whole distribution has shifted and the top of a bad batch still looks "best."
Some teams go a step further and train a separate model whose only job is predicting whether an extraction meets a baseline accuracy standard, rather than trusting the extraction model's own self-assessment. Intuit's patented metamodeling approach works this way: a confidence meta-model is trained on ground-truth labeled data, tested on a held-out set, and only then used to route documents between automated and manual handling. The score driving the routing decision isn't the extraction model grading its own work.
Embedding-based verification offers another path to the same goal. LLM self-critique, where a model is asked to judge its own output, tends to agree with itself far too often. Classifying extraction results using embedding vectors instead produces a meaningfully better F1 score at telling correct extractions apart from erroneous ones. That gives a queue a way to flag fields for human review without depending on the same miscalibrated probability that caused the problem in the first place.
How calibrated thresholds translate into a tiered routing queue
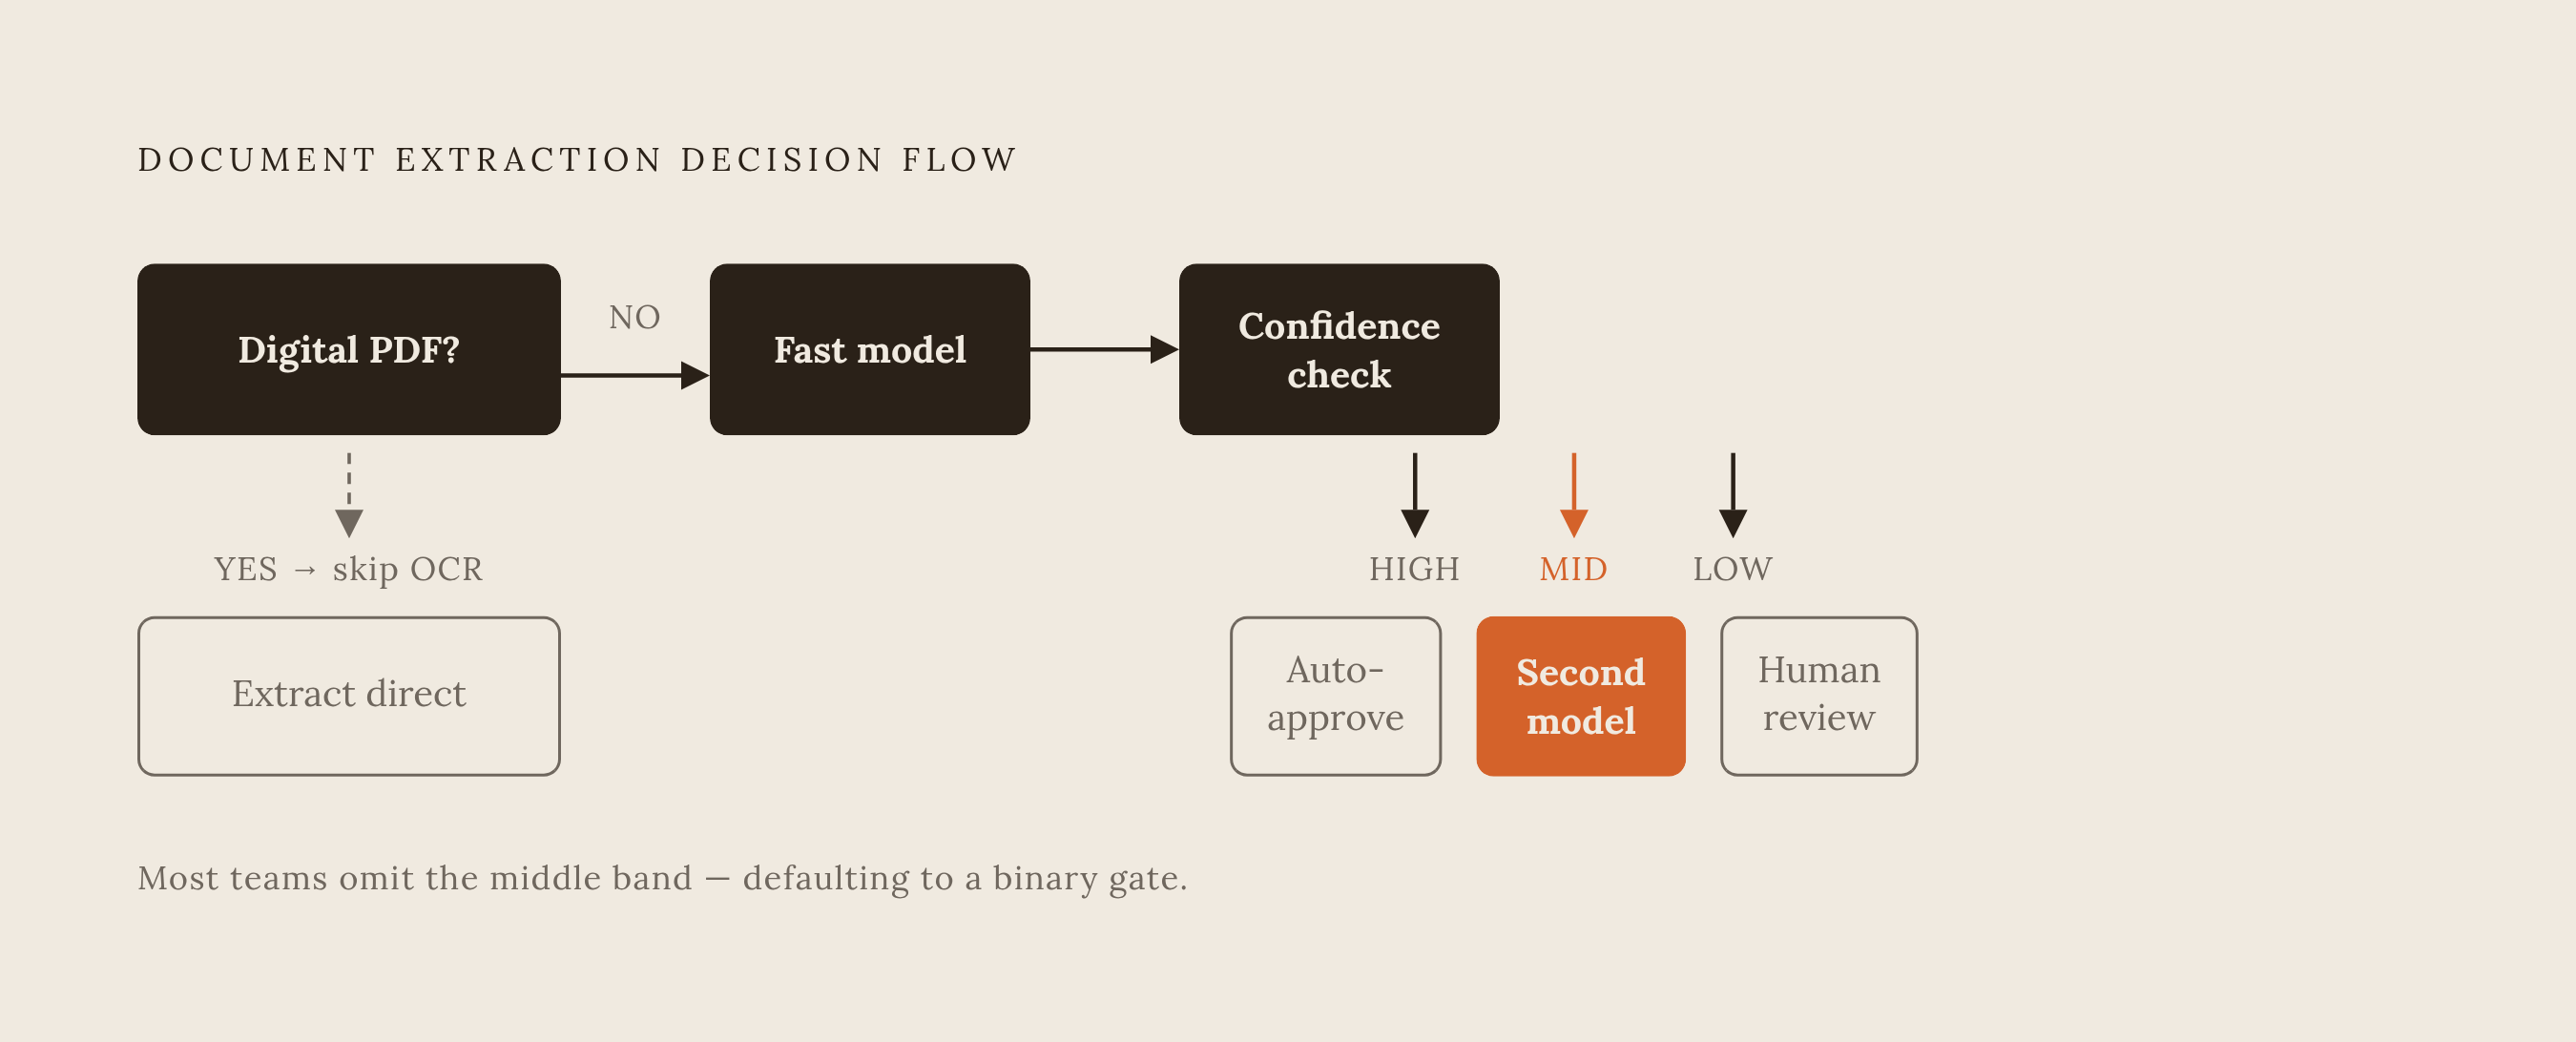
Once a threshold has been calibrated per field and per document type, it stops functioning as a simple pass/fail gate and becomes a routing signal, sending each field down one of several paths depending on the cost and risk attached to that confidence band.
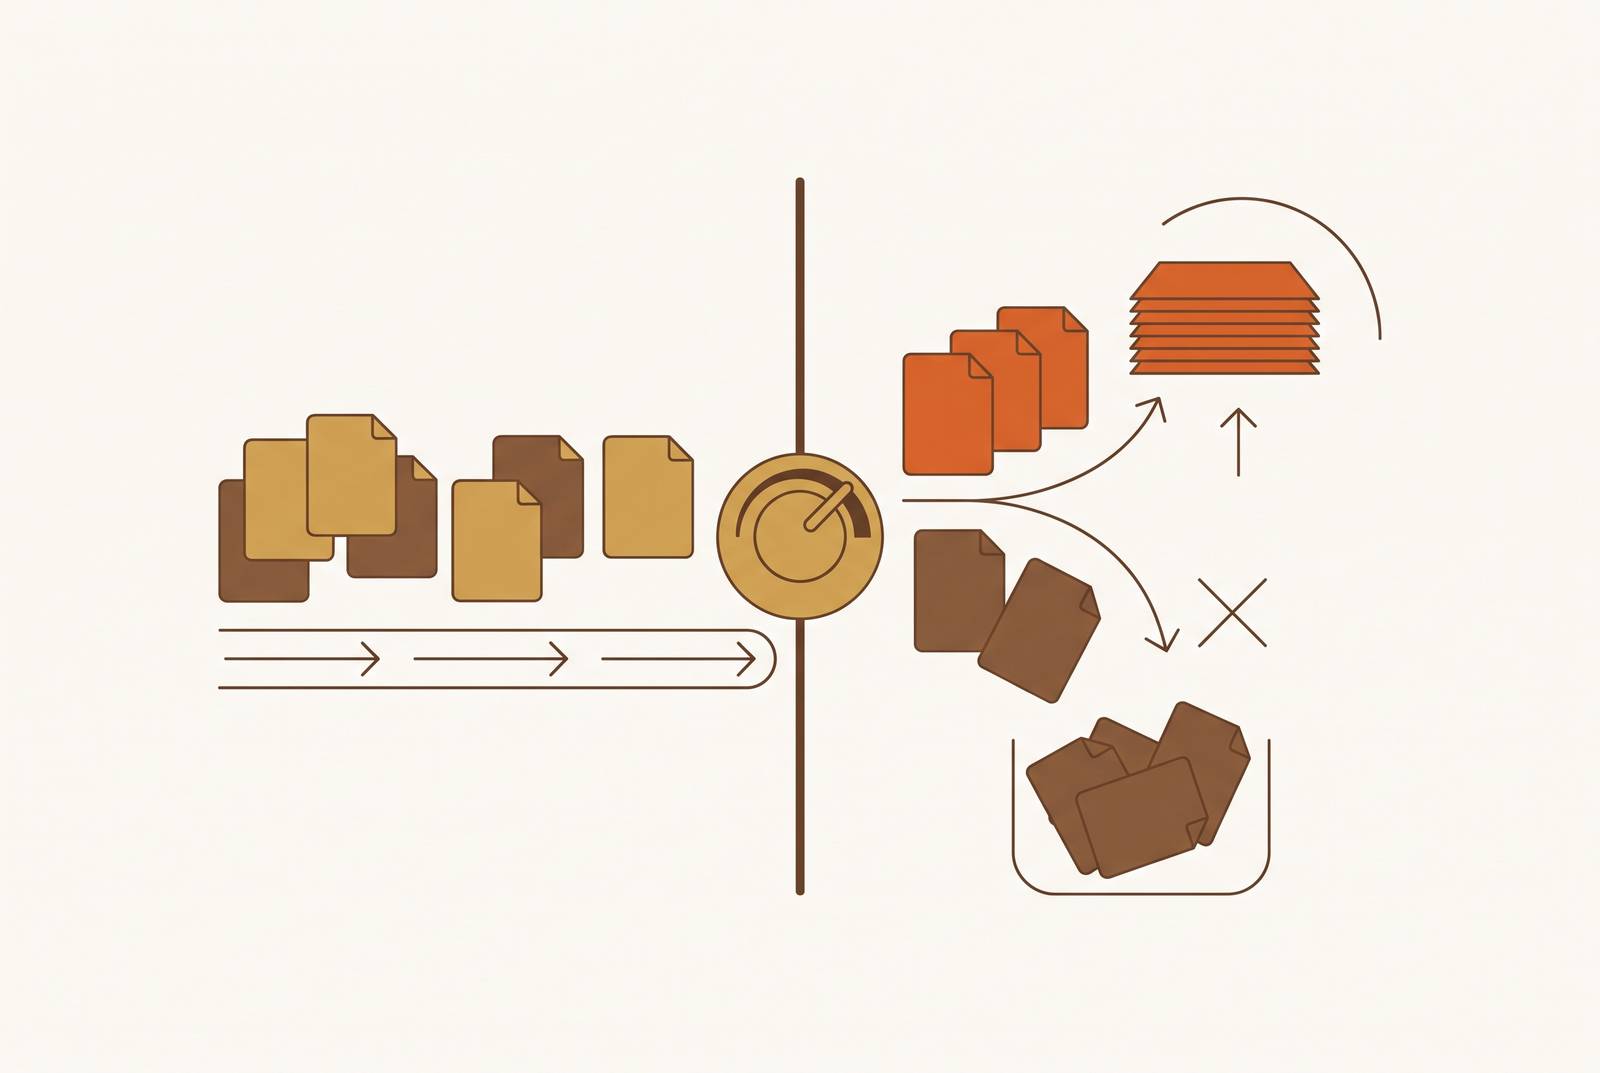
A well-built queue runs this logic in order: check first whether the document is a digital-native PDF with embedded text, and if so, skip OCR entirely. Run a fast, cheap model against the bulk of clean traffic. If the resulting confidence clears the high-accept threshold, you approve the field automatically. If it lands in a middle band, escalate to a more capable (and more expensive) model for a second pass. If it falls below the low threshold, send it straight to a human reviewer.
This tiering is also a cost architecture. OCR is often the actual bottleneck in the pipeline, because it has to process every page of a document separately while the language model can take in the whole document in a single call. Routing clean, digital-native documents around the heavy OCR step changes throughput as well as accuracy, so the skip-OCR check belongs in the design from the start.
The order of operations here matters more than most teams realize. A business picks its acceptable error rate first, call it alpha, the rate of mistakes it can tolerate among automatically accepted fields, and the threshold gets derived from that choice on a held-out calibration set. Most teams do this backward: they pick a threshold that feels reasonable, deploy it, and only later discover what error rate it's actually letting through. The correct order starts with a business decision about tolerable risk, with the threshold as math applied to that decision.
The Intuit metamodeling patents follow this same structure at the routing level: the decision of whether a document goes to automated or manual extraction is based on a predicted probability, fit to ground truth, that the automated result clears a baseline accuracy bar, and documents scoring above that threshold go automated while documents below it go to manual review.
Everything below threshold belongs in human review: it's the destination the gate is designed to produce whenever a field's calibrated score doesn't support the accuracy guarantee the business has committed to. A pipeline with no credible human review path is hiding its own uncertainty inside a number that looks more confident than the evidence supports, no matter what threshold it claims to use.
Field-level confidence calibration as a compliance requirement
In regulated industries, running a document pipeline on uncalibrated confidence scores can cost you more than accuracy. The same frameworks that govern automated decision-making already require the audit trails and human oversight that calibration is built to produce.
Under GDPR, decisions that carry legal or similarly significant effects on a person can't be made by fully automated means alone, and human review is generally required for decisions that fall in scope, with a small set of exceptions. A calibrated threshold that routes low-confidence fields to a human reviewer is the mechanism that satisfies this rule. An uncalibrated threshold that auto-accepts fields it shouldn't have confidence in is the mechanism that breaks it.
SOC 2 auditors increasingly expect to see audit trails covering AI-specific failure modes, including model drift, hallucination, and training-data leakage. These expectations come from auditors who apply the existing Trust Services Criteria through practitioner judgment, because the AICPA hasn't yet published authoritative AI-specific standards. Even without a formal AI-specific rule on the books, a field-level confidence score with a documented calibration history, tied to ground truth and reviewed on a schedule, is the artifact an auditor can actually trace. A raw model score with no ground-truth validation behind it gives an auditor nothing to check it against.
Calibration is the condition that makes "works" a claim anyone outside the engineering team can verify.
Sources
- Embedding Confidence to Enhance Trust in AI Document Entity Extraction
- 1. Introduction
- Valid Per-Field Selective Risk Control for Document Extraction: Three Failure Modes, a Validity Ladder, and When Conditioning Pays
- Perception, Layout, and Validation: Calibrated Confidence for Reliable Straight-Through Processing of Financial Documents