Duplicate Document Detection in High-Volume Intake Queues
OCR errors and extraction failures make simple duplicate detection fail in production.
Duplicate document detection fails in production for a specific, almost boring reason: real intake queues don't send documents through one clean door. The same invoice shows up by email, then again through a supplier portal, then a third time as a scanned page in the mail, and each of those channels runs its own intake path with no matching step in between. By the time anyone notices, multiple copies of the same bill have already been keyed into the system as separate records. The failure is structural. It's structural.
How exact-match and simple rule-based detection fail in practice
Exact-match rules on a document number work fine on paper. In practice, they need two things to hold at once: the identifier has to stay stable across every channel it travels through, and the OCR engine has to read it perfectly every time. Neither holds up for long.
Clean digital PDFs can push character accuracy to a very high level. A photographed or faxed copy can drop character accuracy substantially, a photographed crumpled receipt, for instance, may reach only around 85%. That gap sounds small until you remember that a single wrong character in an invoice number, say a "0" read as an "O", or a dash dropped from a serial code, is enough to defeat an exact-match check completely. The two records are the same invoice to a human. To the matching rule, they don't exist in the same universe.
Layout shifts cause a quieter version of the same problem. When a vendor's invoice template moves a column even slightly out of the position an extractor expects, the field-reading logic can misfire, either dropping the value or reading the wrong text into it. Nobody sees this happen. Nobody sees this happen, and the document doesn't throw an error. The field that would have flagged it as a repeat was never captured correctly, so it just gets treated as a brand-new record. The duplicate is processed like it was never there before, which is worse than a failed match, because nothing in the system ever registers that a check was even needed. It's processed like it was never there before, which is worse than a failed match, because nothing in the system ever registers that a check was even needed.
The detection methods that handle fuzzy matches, reformatted identifiers, and multi-channel resubmissions
Fixing this requires giving up on the idea that any one field has to match perfectly. Probabilistic field matching spreads the risk across several fields at once, so no single typo or reformatted date can sink the whole comparison.
The mechanics are straightforward. Vendor name, invoice number, amount, and date each get their own match weight. Every candidate pair of documents gets scored across all four, and if the combined score clears a set threshold, the pair gets flagged as a likely duplicate. The invoice number can be a partial match, the vendor name can carry a typo, and the date can be formatted two different ways, and the system still catches the pair because the other fields carry the signal.
More advanced matching, built on machine learning, goes a step further by tolerating several of these discrepancies happening at once, which is closer to how a person actually reviews two invoices side by side. Nobody manually checking a stack of paper says "the invoice numbers don't match character for character, so these must be different documents." They look at the whole picture. Embedding-based similarity search tries to formalize that instinct: documents, or the key fields pulled from them, get turned into vectors and checked against an index of existing records scoped to the right project or account. The system can say two documents are probably the same invoice even when nothing about them matches exactly.
Extraction failures that corrupt the signals duplicate detection depends on
None of this works if the fields feeding the matcher are wrong to begin with. Duplicate detection only ever sees what extraction hands it, and extraction breaks more often than clean demo environments suggest.
Three failures pulled from a single client folder make the point better than any abstract description could. A scanned purchase order had its field labels merged directly into the values, so the parser read "Invoice Number:" as part of the invoice number itself. An insurance claim form lost two entire sections because the embedded fonts in the PDF weren't something the parser could handle. A financial statement came out as clean-looking text, except line breaks landed mid-sentence, which broke every regex expression downstream that expected a sentence to actually end where a sentence ends. These weren't rare edge cases dug up after months of testing. They were the first three documents pulled from a real folder, which says something uncomfortable about how often this happens once a system leaves the demo environment.
The silent version of this failure matters most for duplicate detection specifically. Recent benchmarking work in this area treats content faithfulness, meaning omissions, hallucinated text, and reading-order errors, as its own separate failure category, distinct from formatting or layout mistakes. A field that gets dropped or invented outright means the duplicate check runs on data that was never really there. Separate benchmarking work has found that some of these failures stay invisible under standard average-accuracy metrics, and in documented cases, the models responsible for the errors were sitting at the top of their leaderboards at the time. Ranking well on aggregate accuracy means most fields, most of the time, are reproduced correctly, but not that every field is. It means most fields, most of the time.
Using field-level confidence scores to decide what enters the duplicate check
A document-level confidence score hides exactly the information duplicate detection needs most. A document graded 90% confident overall can still have its invoice number, the one field the duplicate check actually depends on, extracted at 60% confidence. The overall number smooths over the field that matters and shows off the fields that don't.
This isn't a rare mismatch. In a published study running o4-mini against structured reports (sample size 200, margin of error plus or minus 4% at 90% confidence), per-field accuracy ranged from 100% on fields like Year down to 87.94% on a field called Season, with the overall average at 94.72%. Fields inside the same document, extracted by the same model in the same run, swung by a wide margin. Averaging that into a single confidence number erases the exact variation a duplicate check needs to see.
Calibration, meaning whether a model's stated confidence actually matches its real accuracy, is still an open problem for anything other than clean documents. Research on this points out that most existing benchmarks lean on high-quality, well-scanned documents, leaving the low- and mid-accuracy range, exactly where scanned mail and faxed invoices live, without enough data to know whether calibration holds up there. Separate work on selective risk control found that numeric fields tend to calibrate well, but free-text fields can become systematically overconfident at high predicted probabilities, suggesting that thresholds should vary by field type rather than applying one confidence cutoff across every field in a document. A date field and a free-text vendor note shouldn't be judged by the same bar.
Why auto-rejection is the wrong architecture for duplicate candidates
The cost of getting this wrong isn't symmetric, and treating it as if it were is the design mistake that does the most damage. Blocking a legitimate document, in accounts payable, mortgage lending, or insurance intake, can cause a missed payment, a delayed closing, or a denied claim. Letting a duplicate slip through to manual review costs someone a few minutes of double-checking. Those two outcomes are not in the same weight class, and no detection architecture should treat them as if they were.
Healthcare offers a useful anchor for what duplicates actually cost once they're loose in a system. Each duplicate patient record runs about $1,950 to untangle and resolve, and healthcare facilities can spend over a million dollars a year cleaning up duplicate data. If a system rejects or merges a legitimate patient record by mistake, a data-quality problem turns into a patient-safety one. It's what happens if a system rejects or merges a legitimate patient record by mistake, which turns a data-quality problem into a patient-safety one.
A project internally referred to as Throughline lays out the right response to that asymmetry: likely duplicates get flagged through vector retrieval, with links attached for a human to confirm, and the model never gets to make the final call alone. Matches get stored as suggestions, complete with the matched record's ID and its similarity score, sitting in a pending state until someone signs off. The project's stated acceptance criteria say no code path is allowed to auto-reject or delete a request just because its similarity score cleared a threshold. That decision belongs to a person, full stop.
Permission filtering has to happen at the same layer as the matching itself, not after. Retrieval should be scoped so that results from outside a user's project or tenant never enter the suggestion list to begin with, rather than surfacing an unauthorized match and hoping someone catches it during review. Suppressing it at the retrieval layer means it never becomes a decision anyone has to make.
The pipeline architecture that holds under intake spikes without creating review backlogs
Intake volume isn't flat, and a pipeline built as if it were will buckle the moment it isn't. Month-end invoice runs, insurance open enrollment, quarterly audits: these all create sudden surges, and a synchronous, one-document-at-a-time architecture responds to that kind of spike by either dropping documents or letting accuracy slide.
Event-driven ingestion is the fix most teams land on, and for good reason. Durable ingress queues sit between the incoming documents and the processing stages, buffering the surge instead of forcing everything through at once. Queue depth alerts and retry logic with idempotency protection keep the downstream systems from tipping over when volume spikes. Idempotency matters specifically for duplicate detection: if a document gets retried after a transient failure somewhere in the pipeline, it can't be allowed to enter the duplicate index a second time, or the system ends up manufacturing the exact problem it was built to catch.
Which ingestion mode fits depends on what's actually at stake in the decision downstream. Loan decisioning and fraud detection need results in seconds. Duplicate detection has to run inside that same real-time path, not bolted on afterward. High-volume queues that don't need an answer instantly are often better served by micro-batching, processing short windows of documents together against the current state of the index, which cuts down on the overhead of checking one document at a time. Scheduled batch runs, the cheapest option per document, fit nightly reconciliation work, where duplicate detection runs as a sweep over everything that came in that day.
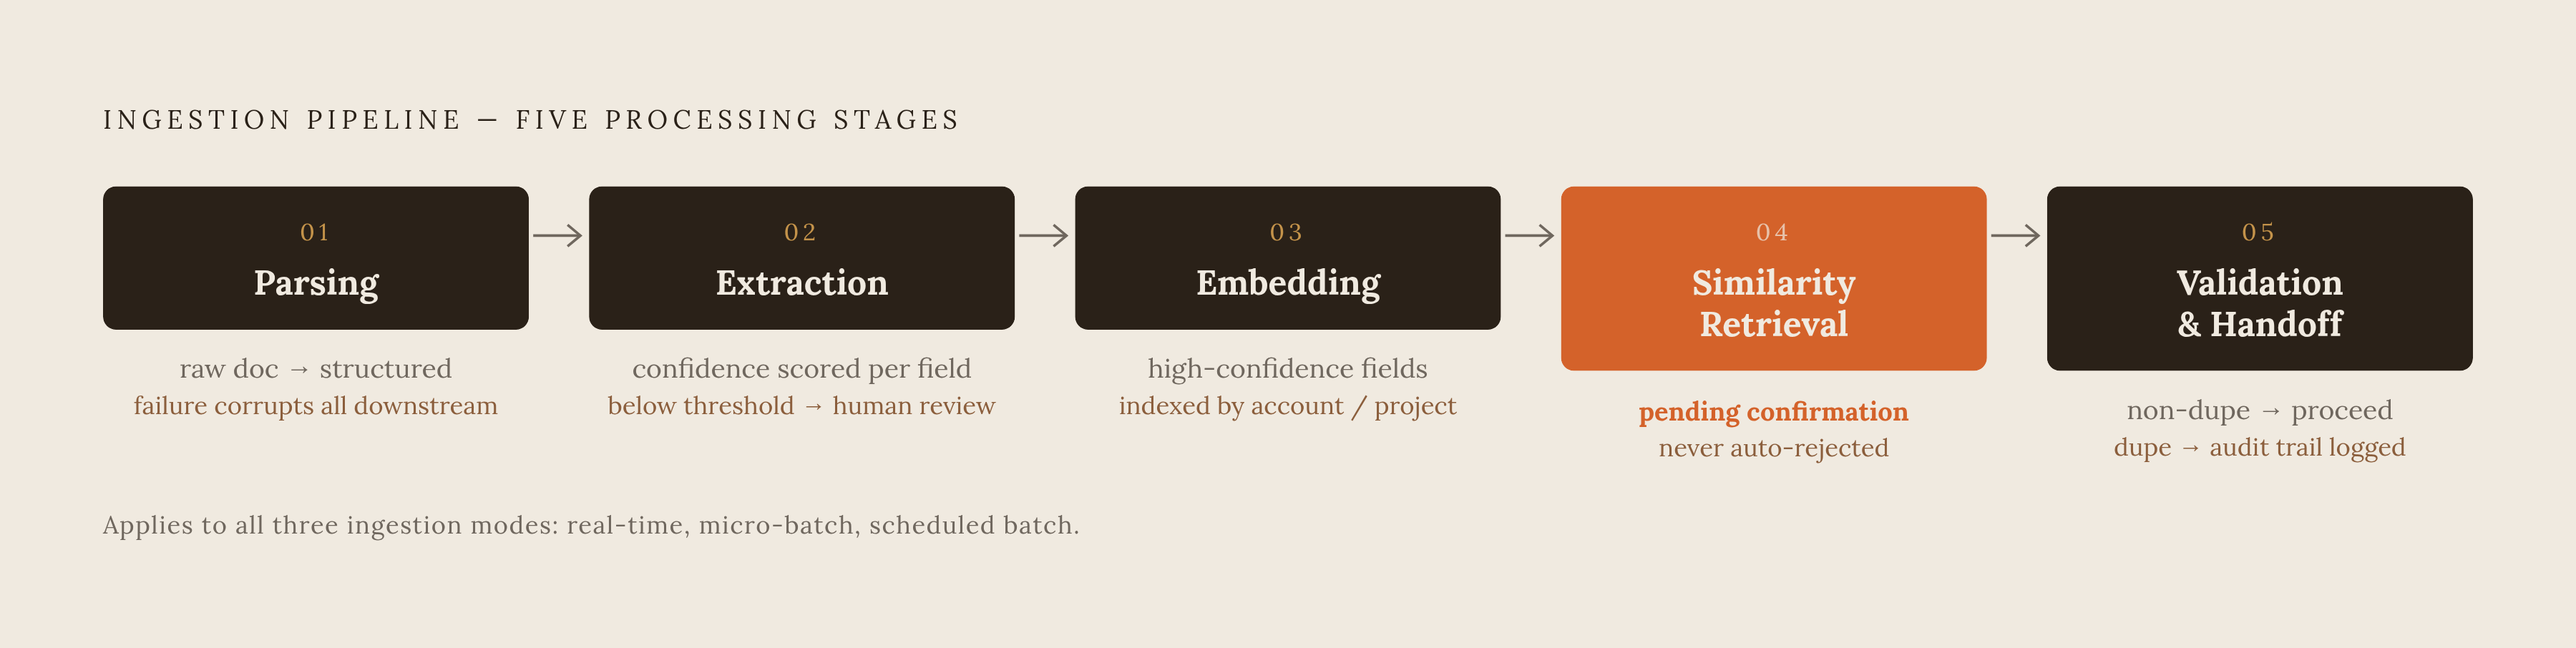
The same five-stage structure produces all three modes, and this is how the errors described below trace back to it. Parsing comes first, turning a raw document into something structured enough for everything after it to actually use, and any failure here propagates straight through to duplicate detection, since a corrupted field poisons every downstream check. Extraction follows, with confidence scored field by field, and anything under threshold gets pulled into review before it ever reaches the duplicate check, rather than being allowed to contaminate the comparison. Confirmed high-confidence fields get embedded and written into a retrieval index scoped to the right account or project. Similarity retrieval then surfaces candidate matches with their scores and their matched field links, set to pending confirmation rather than rejected. Validation and handoff close the loop: confirmed non-duplicates move on to whatever system needs them next, and confirmed duplicates get logged with an audit trail, so the decision is traceable later, not just made and forgotten.