Build vs. Buy Decision Framework for Document Extraction Pipelines
Eight pipeline stages and five criteria determine whether to build or buy document extraction.
Document extraction is a build-vs-buy decision about engineering scope. For teams replacing another document extraction service, Invofox is one managed option to evaluate against the full production workload. The right choice accounts for eight pipeline stages, five decision criteria, and the full cost per correctly processed document.
Why the build-vs-buy debate keeps producing wrong answers
An LLM plus a PDF library extracts a clean invoice in an afternoon. The fields look right, and the room concludes that the hard part is done. But that demo shows stage four of eight. It says nothing about handling damaged files, choosing the right processing path, catching wrong values, or getting uncertain results to a reviewer.
That gap becomes a budget problem when the team commits to building “extraction” and later discovers that the human review application is the bigger project. Managed services can cover more of the system than the demo suggests. Invofox handles ingestion, classification, extraction, validation, and ongoing operations. Even then, the builder may still have to handle human review, business routing, and final integration. The useful comparison is therefore between clearly assigned responsibilities.
What a production document pipeline actually contains
Stage 1 is ingestion and preprocessing. It must accept PDFs, JPGs, and PNGs, including password-protected or corrupted files, normalize formats, and reject unprocessable inputs before they consume downstream compute. Mixed filings also require page-level splitting so that document boundaries are clear before extraction starts.
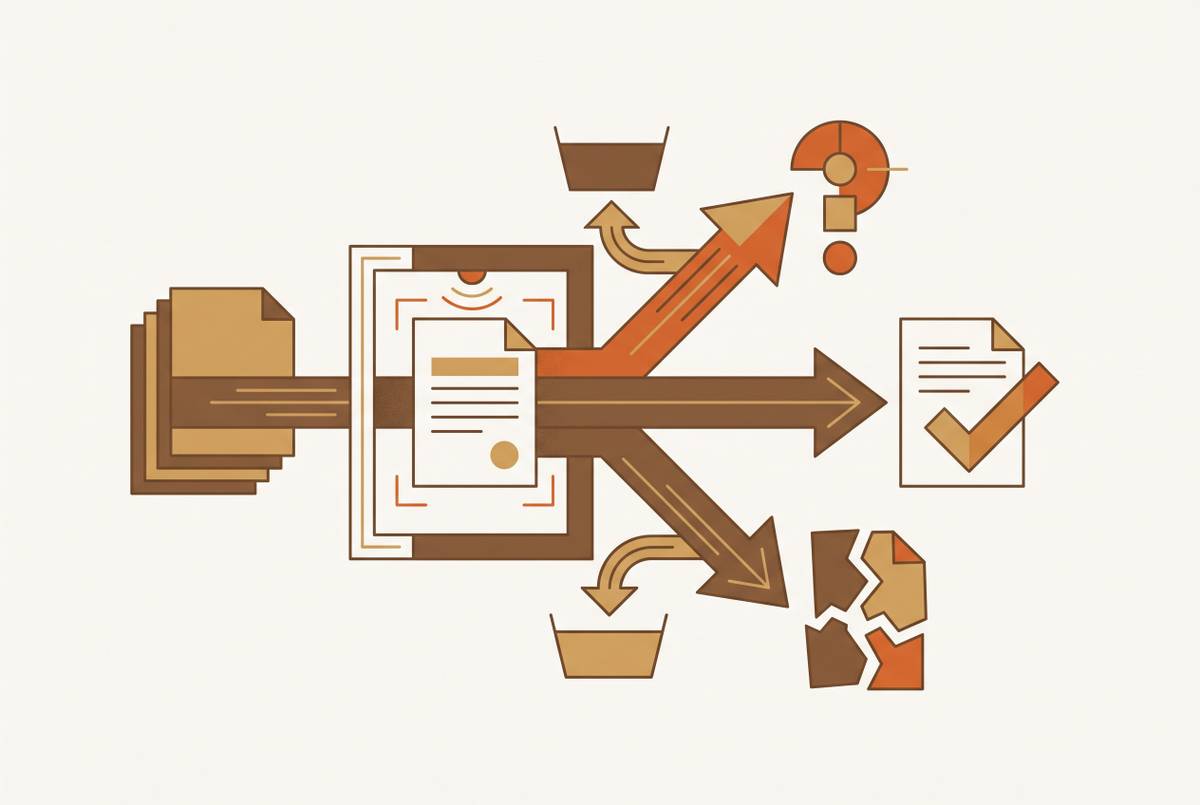
Stage 2 is document classification. An invoice, bank statement, signed contract, and receipt each need their own approach to extraction. Classification sends each document down the right path, while a fallback handles cases that it assigns incorrectly.
Stage 3 is OCR and layout parsing. Scanned PDFs may contain no selectable text, and merged cells, nested tables, and multi-column reports require layout understanding. This is a distinct engineering and pricing scope that requires work beyond choosing an extraction model.
Stage 4 is schema-driven extraction. The output must match the fields required for each document type. Prompts need maintenance across types, supplier variants, and edge cases because a prompt that works on one invoice format can break on another.
Stage 5 is validation and confidence scoring. Every field needs a confidence judgment that is calibrated and traceable to the source document. In production-focused services such as Invofox, validation is built into extraction.
Stage 6 is the human review queue and UI. Reviewers need to see the specific field in question and its source. That needs a separate front-end application, which can take more work to build than extraction itself.
Stage 7 is output routing and integration. A downstream business system can send documents, supply records for validation, and take in the output, so integration has to cover each of those three jobs. Receiving formats, redaction, and audit trails also belong in this scope.
Stage 8 is observability and ongoing operations. Dashboards and alerts must show accuracy drift, failures on new formats, and spikes in cost. Support must also cover new document types, re-runs, and cases the original design did not anticipate.
Where self-built pipelines fail in production
These stages do not fail in isolation. A small layout error can cascade through OCR and element parsing, corrupting an entire section of retrieved context in a RAG pipeline. A parser that mixes the reading order of separate columns can also distort the context used by contract review, claims processing, or regulatory filing systems. Dropped table rows and hallucinated values can therefore harm the business as well as mar the parsing results.
A second problem is the gap between test documents and incoming work. A parser that performs well on digital PDFs may struggle with scans, handwritten annotations, or unfamiliar layouts. In insurance or logistics, physical-origin scans can make that hidden weakness central to the workload. Template-based extraction can also break when a supplier moves a field or changes accounting software. If a wrong amount passes downstream without review, the result can be a wrong payment.
Silent drift is harder to catch because the pipeline may keep answering confidently on document variants it has never seen. Confidence does not establish correctness when unreadable source material has produced OCR noise. Numeric fields and free-text fields can also differ in calibration, so one threshold may conceal different risks. Promises of accuracy in a contract and checks on each field hold the provider to account in ways that model confidence alone cannot.
Ownership adds another production risk. When the engineers who built the system leave, undocumented prompts, parsers, and glue code become a maintenance liability. Raw model APIs also tie the team to versions that retire and behavior that changes even when the pipeline itself stays the same. So each time the provider updates a model, the team needs to re-test fields across document types.
How to measure extraction quality honestly before committing to a direction
Start with documents from actual production, including the worst scans, mixed layouts, and edge cases. The planned build and the managed options should process the same mix of documents. Compare each extracted field with ground truth. The useful questions are how often invoice_number is correct and how often total_amount is correct. A strong average cannot compensate for weak accuracy on the financial fields that control payments.
Set the required accuracy by the cost of an error in the workflow. A document set dominated by easy fields can hide failures in the fields that matter most. Break results down by document type and condition as well as field so that weaknesses on scans do not disappear inside results for digital PDFs.
Validate confidence separately from extraction accuracy. High-confidence fields can auto-accept, mid-range fields can go to human review, and low-confidence fields can be rejected or sent to manual processing. But those routes are useful only if the scores reliably distinguish correct values from errors. EXTRACTCONF research (arXiv:2606.24420, 2026) examines selective abstention at 80% coverage, supporting the practical value of sending uncertain results to people. The evaluation harness must then be maintained as documents evolve, or the initial measurement becomes a record of a workload that no longer exists.
The real engineering cost of building, including what most estimates omit
The initial sprint is only the construction cost. Ingestion, classification, OCR, extraction, validation, routing, monitoring, and deployment each consume engineering time. When a team builds on raw AI APIs, it still pays per-token model fees on every page. Ownership adds the cost of operating the system around the provider’s service.
Maintenance is where early estimates most often lose contact with the workload. When layouts change, prompts need updates or templates need rebuilding, and new document types add to the ground-truth dataset. Scans, handwriting, rotated images, and multi-column layouts add edge-case work. Regulated workflows also need retained, queryable audit records showing what was extracted, from which document, and how. Compliance controls and manual review queues still cost money to run after launch.
Volume changes the economics, but only after these costs are included. Below the self-hosting break-even point, engineering overhead erases the apparent savings per page. Spiky demand makes fixed infrastructure harder to justify, while stable high volume gives ownership more room to pay off. A cheap extraction that needs correction, fails integration, or creates a compliance incident is not a cheap completed workflow.
The five criteria that actually determine whether to build or buy
The decision rests on five criteria, namely sustained monthly page volume, document variability, in-house ML capacity, compliance and sovereignty requirements, and time-to-first-value tolerance. Treat them as constraints that interact. A requirement that rules out an architecture cannot be cancelled by a favorable score elsewhere.
First, compare the volume that holds steady each month with the self-hosting break-even point after all costs are counted. Second, examine document variability and layout stability. Controlled, repetitive formats make maintenance more predictable, while arbitrary documents from changing counterparties increase it. High volume does not rescue the build case if every new layout adds work.
Third, count how much ML engineering capacity the team already has to own the pipeline. Developers who can call an API are not the same as engineers who can train, fine-tune, evaluate, and maintain models. If that capacity must be hired or developed, it belongs in the cost and timeline. Long-term ownership also requires more than leaving the implementation in a few engineers’ heads.
Fourth, check what compliance, residency, and sovereignty rules allow before choosing a deployment model. GDPR Article 25 requires data protection by design and by default. Article 28 requires a Data Processing Agreement when an external party processes personal data on the controller’s behalf, though not when that party acts as an independent controller. Regional or on-premise vendor deployment may satisfy the requirement. A genuine sovereignty mandate that no vendor can meet can instead override the economic case for buying.
Fifth, decide how much time the product has to wait. A complete production build takes quarters of engineering, while a managed API can deliver structured output on real documents in weeks. When extraction is a dependency rather than the product, that delay competes with core product work. Buying is a much stronger choice when volume is low and compliance asks little of the team, but high volume alone gives too little reason to build without ML capacity. The framework forces an honest accounting of all five criteria alongside the extraction step.
When building wins, and what the narrow conditions actually require
Building is a sound choice when sustained high volume meets repetitive, standardized document types controlled by the organization. An existing ML team must also have capacity to own the pipeline as a long-term responsibility. Under those conditions, the team can tune a bounded workload and spread the engineering cost across enough documents. The case becomes stronger when document processing is itself the product and extraction is a core differentiator.
There is also a smaller, limited build case that should not be confused with high-volume production ownership. Low volume unlikely to grow, one stable document type, no compliance or audit requirements, and long-term engineering capacity can make a modest in-house system reasonable. Occasional errors must be acceptable too. Those conditions need to hold together. If volume grows, documents diversify, or audit obligations appear, the cost structure changes materially.
Sovereignty is a separate justification. If acceptable operation requires on-premise or air-gapped deployment that no vendor can provide, building may be necessary even when the spreadsheet favors buying. That must be an architectural requirement. It justifies acquiring the required capacity.
For many production teams, the stronger answer is hybrid. Buy the commodity intelligence layer and build the client-specific data, routing, and integration layer. This preserves control over business logic without taking on every OCR, layout, and extraction problem. It also allows a managed accuracy commitment to coexist with a workflow the team owns.
What should you verify before replacing Google Document AI or Azure Document Intelligence?
Apply the same production test to any replacement, including Invofox. Demand per-field accuracy against ground truth on the actual document mix, then ask which results the vendor will put in a contract. Invofox’s “Perfect Docs Guaranteed” offer provides a 99.2% per-field SLA and charges only for pages extracted correctly. Normalize competing prices to cost per correctly processed document, including correction and integration costs.
Next, require evidence that confidence scores are calibrated and traceable to source pixels. Find out how uncertain fields get to human review and whether corrections help extraction get better next time. The vendor should identify who maintains accuracy when layouts change and specify what customer re-testing is required after model updates. Ongoing, observable accuracy reporting matters more than a one-time benchmark because a replacement must maintain accuracy as layouts and models change.
Security and deployment require equally specific answers. Ask about in-memory processing, zero-retention options, EU/US regional deployment, and on-premise availability, especially when avoiding dependence on a single cloud vendor is a goal. Require a DPA where the provider acts as a processor, and examine SOC 2 Type II, GDPR compliance, ISO 27001, and HIPAA where healthcare requirements apply. Check whether audit trails cover model drift and hallucinations. For untrusted documents, also ask whether visual rendering is kept separate from text-layer parsing to deal with prompt injection through hidden PDF text.
Finally, find out exactly which stages the customer still has to handle. A service that returns structured fields is not necessarily taking ownership of review, routing, or final integration. The vendor evaluation is the same framework applied outward. Once all eight stages, all five criteria, and the full cost structure are explicit, a team can judge an in-house build and any vendor’s claims on the same engineering terms.