Evaluating Document AI Vendors on Edge Case Handling
Benchmark scores hide real failures on the documents your operation actually processes.
The leading document extraction platforms both post strong benchmark numbers, and both still fail on the documents that actually move through a production pipeline: degraded scans, multi-column tables, a supplier's one-off invoice layout. The real alternative is a platform you've tested against your own hardest documents, with per-field accuracy measured against ground truth, confidence scores you've verified are calibrated, and a commercial structure (pricing, SLA) that puts the vendor's money behind the claim. That's the evaluation standard this piece lays out, and it's the standard that separates a genuine production replacement from a demo that scored well.
Why benchmark scores don't predict production failures
Procurement teams default to benchmark tables because they're the easiest thing to compare. The problem sits earlier than the comparison itself: that benchmark was built from someone else's document mix, tested on someone else's scan quality, and scored against someone else's definition of "correct."
The question that actually predicts production performance is which parser handles the documents your operation produces: scans at inconsistent resolution, invoices formatted by hundreds of different suppliers with no shared template, batches that arrive by the dozen some days and by the thousand on others. Most public document benchmarks skew toward clean, digital-native pages, for a simple reason: clean documents are cheaper to annotate and more abundant in the datasets researchers can access. If a parser trained mostly on that kind of document posts a strong aggregate score, it can hide real weaknesses on scanned paper, handwritten annotations, or multi-column layouts it never saw enough of during training.
That gap between benchmark rank and production behavior comes from somewhere specific: training data that doesn't match your document population. And the gap gets worse, not better, as your edge cases pile up over time. Benchmark scores tell you almost nothing about which half you're buying into.
How production edge cases cause silent failures
Researchers studying this pattern across AI systems call it evaluation blindness: a measurement function produces a value indistinguishable from a non-failing state while the system is actually failing, and nothing in the pipeline flags the mismatch. No alert fires. No dashboard turns red. Trouble appears downstream first, after the damage is already done.
The UK Post Office Horizon system is the clearest real-world case of this pattern. Failures propagated for years before anyone caught them. An uncalibrated confidence score produces this same structure in a document pipeline: the dashboard says healthy, the extractions underneath are drifting wrong, and nothing in the architecture is built to catch the difference.
Three edge-case mechanisms cause this kind of silent failure in document parsing. Multi-page tables are a frequent failure point, and the dangerous errors are the ones that look correct on the page but break reconciliation weeks later; table-level accuracy measured on your own documents predicts this risk far better than a character-level accuracy score ever will. For most enterprise document operations, degraded scan quality, variable lighting, compression artifacts, and physical paper noise are the normal case, not the exception. And every new vendor format or layout variant the pipeline hasn't seen before adds a small failure rate on its own. Those small rates compound. Because nothing throws an error, the overall decline stays invisible until someone downstream notices a number that doesn't add up.
In regulated workflows (accounts payable, mortgage lending, insurance claims) a single misread field turns into a fine, a rejected claim, or an audit finding. The cost of that misread field is whatever decision got made on top of bad data before anyone caught it.
What a structured edge-case evaluation methodology looks like
Test a vendor's demo set, and you learn how the vendor's demo set performs. It tells you nothing about your documents. The fix is to run a proof of concept on your own document population and measure field-level accuracy, not character accuracy and not aggregate document accuracy.
Build that POC on your hardest cases on purpose: degraded scans, the supplier layout your team already complains about, multi-column forms, handwritten annotations. A sample of a few hundred documents pulled from your actual production mix, outliers included, produces more predictive signal than a thousand clean test documents ever could. Your outliers tell you what happens on the share of cases that actually causes trouble.
Score fields, not documents. Measure what percentage of invoice_number extractions came back correct, separately from total_amount, separately from due_date. An aggregate document score averages over the fields that matter most and the fields that barely matter at all, which hides exactly the information you need. The fields with the lowest accuracy in that breakdown are the specific risk area for your operation, and they're different for every business depending on document type and workflow. Check those extracted values against ground truth built independently, ideally by two human reviewers who work from the source document.
Table handling and layout generalization need a dedicated test; they shouldn't be a line item inside a broader accuracy score. Multi-column tables, merged cells, and nested structures are where most parsing tools break down, so test for that specifically instead of assuming a strong overall number covers it. Ask the vendor how they diagnosed what their model still gets wrong; their answer reveals what they did about it. A vendor who inherited a strong score from a large training corpus, without doing the systematic error analysis to find and fix the specific gaps, usually can't answer that question with any detail. The question that separates real engineering work from a borrowed benchmark is how the vendor finds what their model still misses and what changes they made in response.
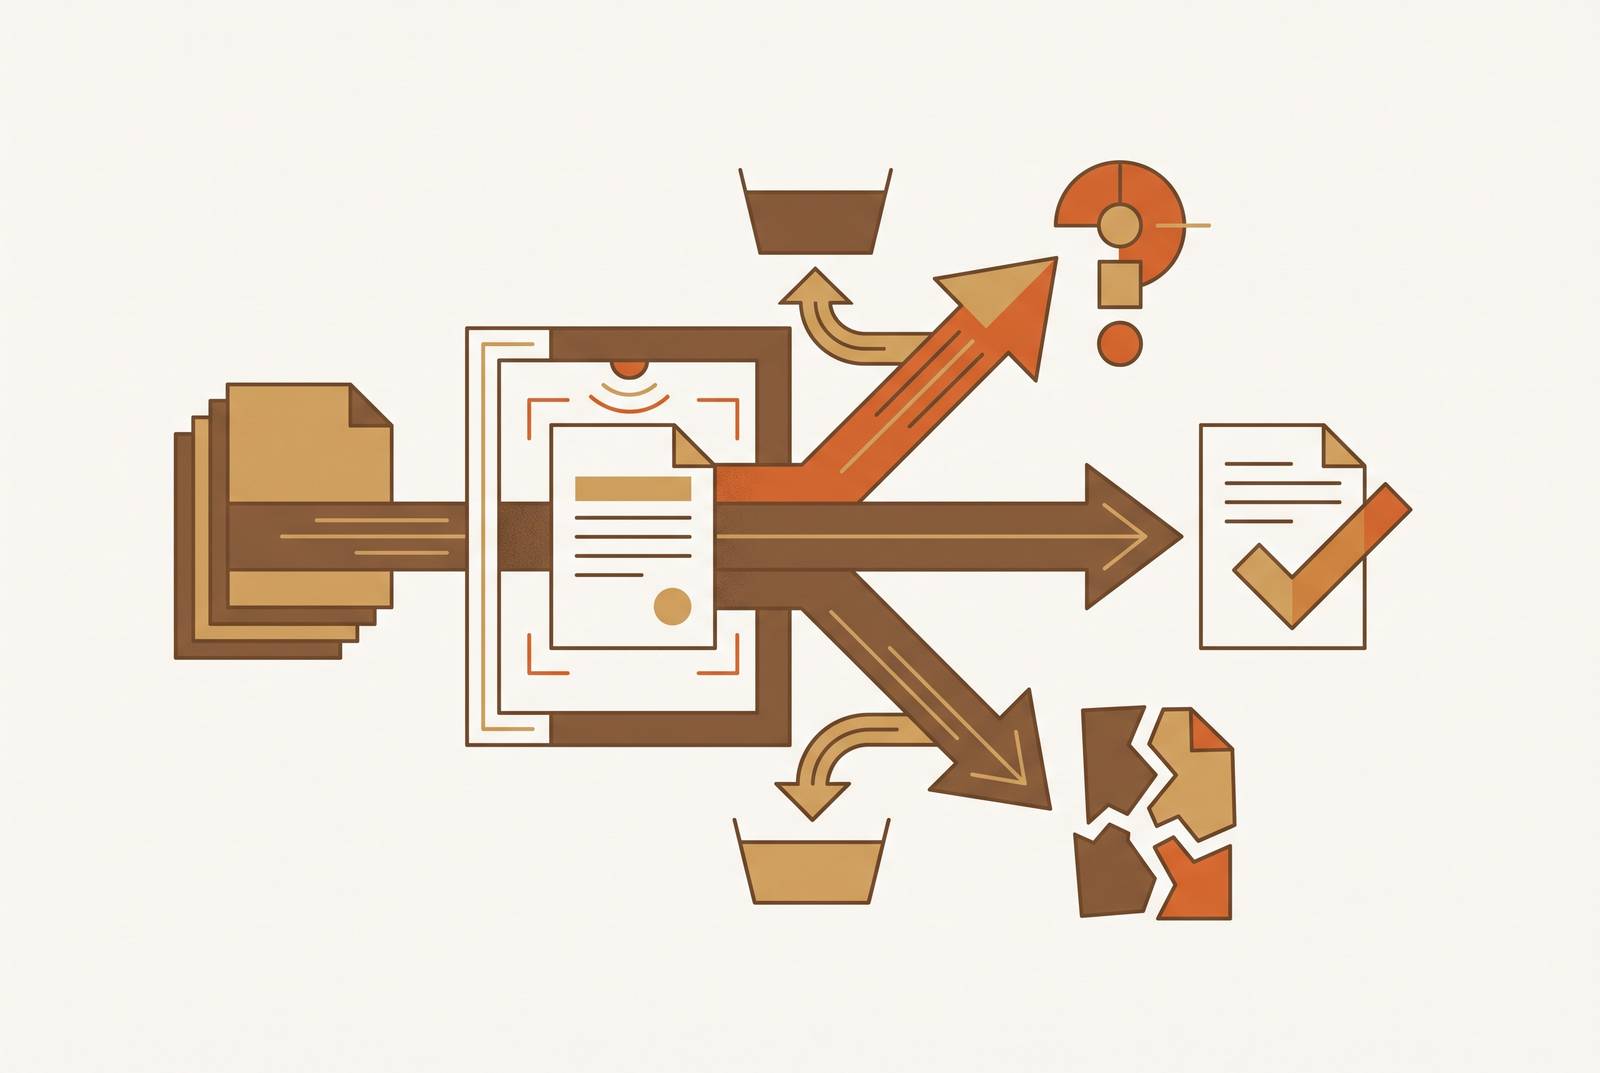
Finally, design the exception path before signing anything. When a document fails at classification or parsing, the system should degrade to manual review rather than push out an unreliable extraction with a confident-looking label on it. Ask for evidence of how the system behaves at the failure boundary, not just how it performs in the center of the distribution where every vendor looks good.
Confidence scores as a routing signal
A confidence score only means something if it's calibrated: a high score has to correspond to comparably high field accuracy at that threshold, consistently. Most vendors report a confidence number without reporting whether that number is calibrated at all, and the two are not the same claim.
When calibration holds, a parser with moderately high aggregate accuracy can function at effectively much higher accuracy in practice, because high-confidence extractions auto-accept cleanly and only the smaller, lower-confidence share routes to human review. Field-level confidence scores are what let downstream systems send uncertain extractions to a human instead of silently passing bad data forward, but only if the score reflects actual uncertainty rather than a number the model produces by default.
The calibration check is straightforward to run on your own POC data: stratify a sample of extractions by reported confidence band, then measure observed accuracy within each band independently. If extractions reported at 0.95-plus confidence aren't landing near-perfect accuracy in that stratified check, the scores aren't calibrated, and they can't be trusted as a routing signal no matter how clean they look on a vendor's marketing page, and this is a test to run against your own documents before any routing logic depends on the result.
Confidence also needs to be traceable, not just numerically consistent. A score worth trusting points back to the specific pixels or text span in the source document that produced it, so a reviewer can audit whether a high-confidence extraction reflects something actually read off the page or a plausible guess the model generated on its own. Vendors who can show that trace give you a way to check the claim. Vendors who can't are asking you to trust a number with no way to verify it.
Silent degradation over time: what happens as new formats accumulate
A vendor can perform well on day one and still degrade over the following year, because the document population a business processes isn't static. New suppliers show up. Form versions change. Regulatory templates get updated. An acquired business unit brings along an entirely different set of layouts the model never saw during training. Each of these introduces formats the system handles worse than the ones it was tuned on, and without continuous measurement against ground truth, that decline stays invisible until a downstream report comes back wrong.
This is the deployment-time version of evaluation blindness: evaluation frameworks fail to catch production failure classes, including the operational failures that are silent by definition. The measurement function keeps producing a value that looks like a non-failing state while the underlying extractions get worse. The mechanism matches what researchers have documented in other AI deployment failures, where a system kept reporting normal operation while its actual behavior drifted away from what the evaluation layer assumed.
Two architectural questions separate vendors who've built for this from vendors who haven't. Does the system surface per-document, per-field accuracy metrics in production, not just during the POC, so drift is visible before it compounds into something costly? And is there a mechanism for routing new, unfamiliar format types to human review while the model hasn't yet learned them, rather than auto-accepting extractions at a degraded accuracy the system doesn't yet know it has?
What a production-grade accuracy commitment looks like
The clearest signal of how a vendor actually feels about their edge-case handling is whether they'll put accuracy in the contract. A vendor who won't is asking the customer to absorb the entire risk of production failures while the vendor keeps the full price of every page processed regardless of outcome.
A contractual accuracy commitment has to be specific to mean anything. It needs to define accuracy per field, not per document. It needs to measure that accuracy against independently created ground truth, not the vendor's own self-reported confidence number. And it needs real commercial consequences attached when performance falls under the agreed threshold, not a vague service-quality clause nobody ever enforces.
Pricing structure is where that commitment either appears or doesn't. A vendor whose pricing ties to correctly extracted pages, rather than to raw pages processed, has built their commercial incentive around getting it right. A vendor billing per page regardless of accuracy has no financial reason to close the gap on your hardest edge cases, because they get paid the same either way. Invofox's pricing model, built around correctly extracted pages with a high per-field SLA, is one example of this structure in practice: customers on qualifying high-volume plans don't pay for pages the system gets wrong, which lines the vendor's incentive up with the customer's actual production requirement.
No contract eliminates every genuinely novel edge case, and no vendor can honestly promise that. A contractual SLA forces the vendor to have a real answer for what happens when performance falls short. It also forces the customer to set their accuracy floor before signing, rather than finding out where it actually sits once the system is already live and a bad extraction has already caused a problem.
Security and data retention as non-negotiable evaluation criteria in regulated environments
Document processing touching financial, health, or personal data comes with a baseline requirement that isn't a differentiator between vendors: zero data retention and certification a customer can actually audit. If a vendor's pipeline runs on a third-party LLM provider underneath, they need to produce contractual proof of how that provider handles data too, because a policy page describing good intentions is not enforceable.
Security questionnaires for AI vendors now go well past a basic data-handling policy. Zero-data-retention has to hold at every layer of that stack, sub-processors included, because a clean policy at the vendor layer means nothing if a sub-processor two steps down retains data the main contract never mentioned.
Hallucination handling specifically has become something auditors ask to see documented. A vendor evaluated for regulated workloads should be able to produce contractual proof, a signed data processing agreement or an enterprise agreement clause, confirming zero retention across their stack, and should hold SOC 2, GDPR, and relevant ISO certifications. On-premise or region-specific deployment options matter for workloads that can't leave a given jurisdiction.
A practical evaluation checklist for edge-case handling before signing
The questions that actually reveal a vendor's edge-case handling don't live on their website. They require structured testing and direct answers about architecture, calibration, drift, and commercial accountability, and they're worth working through in order before any contract gets signed.
For POC design: has the vendor been tested on your own documents, including the hardest cases, degraded scans, unusual layouts, multi-column tables, handwritten fields? Has per-field accuracy been measured against independently created ground truth? Have results been stratified by document type, layout complexity, and scan quality, so you can see exactly where accuracy breaks down?
For confidence calibration: has it been verified that high-confidence extractions actually achieve near-perfect accuracy on your document mix, not just on the vendor's published benchmark?
For security and data handling: can the vendor produce contractual proof, a signed DPA or an enterprise agreement clause, of zero data retention across every layer of their stack, sub-processors included? Do they hold SOC 2, GDPR, and relevant ISO certifications, with on-premise or region-specific deployment available where the workload requires it?
Vendors who answer all of these in specific, verifiable detail have built a system for production. Vendors who can only point back to a benchmark table have built a system for a demo.