Eliminating Manual Review From Invoice and Closing Disclosure Capture in Mortgage Operations
Automating CD and invoice capture requires accuracy, validation, and smart exception routing.
Eliminating manual review from invoice and Closing Disclosure capture in mortgage operations is an engineering problem. An extraction API for mortgage operations at scale needs field-level accuracy, schema validation, and calibrated confidence scores that route exceptions. Those layers let routine documents move without human review and keep fields with uncertain values out of funding.
Why mortgage operations still have a manual review problem after going digital
Signing went digital, but reading the documents did not. Lenders digitized execution and delivery while leaving people to locate fields, compare figures, and enter data into the loan origination system, or LOS. A lender-versus-title Closing Disclosure comparison means reconciling 50–60 line items, and most loans require multiple sessions. That consumes a substantial block of time before anyone resolves a discrepancy. Each session draws directly on the loan margin. E-signature and eClose platforms cannot close this gap by themselves because they digitize execution, while document automation extracts and structures the data that downstream systems need.
The three generations of mortgage automation and where most lenders actually are
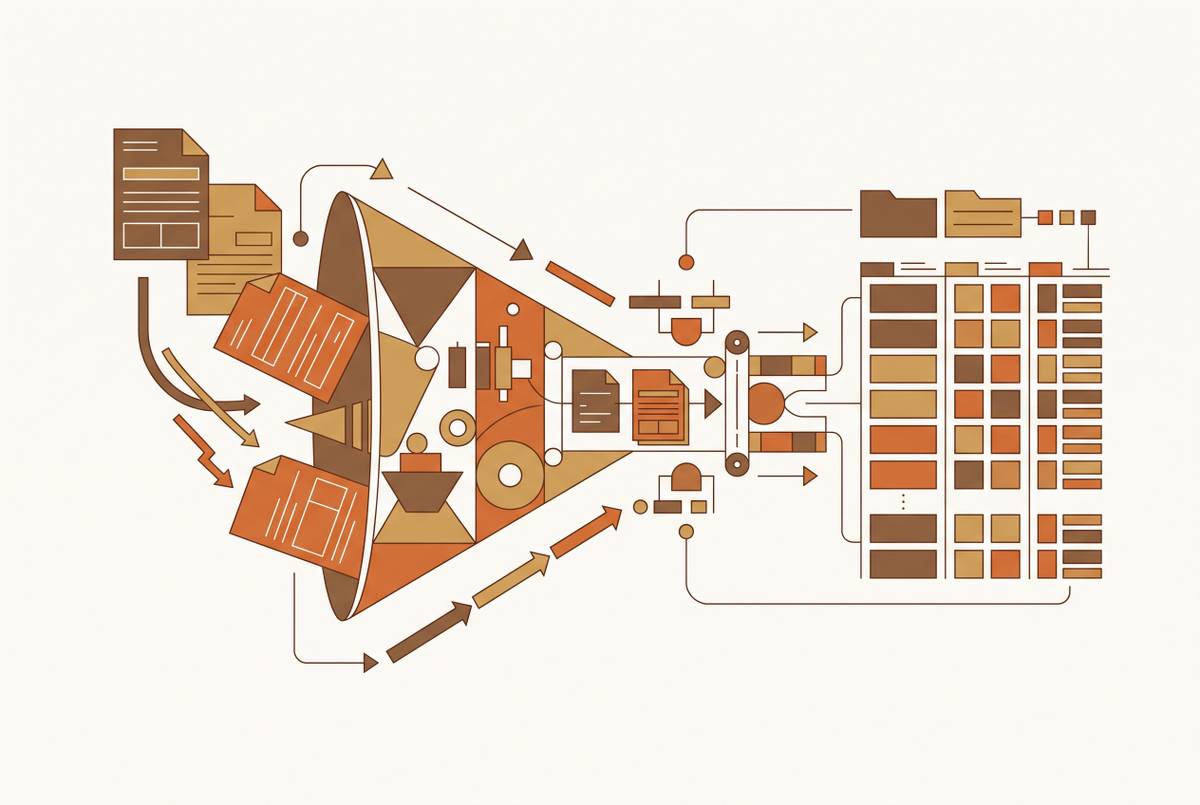
Three generations of automation coexist inside lending stacks. Generation 1 pairs robotic process automation with template OCR, which works when documents have the formats it expects but can fail without warning when layouts change. Generation 2 uses specialized document AI trained on mortgage documents to classify and extract structured data across layout variations. Most serious automation deployments sit here today. This makes extraction more flexible, but that alone cannot show whether a captured fee is safe to use.
Generation 3 adds agentic AI that acts across extracted data without a person running each step. In a closing workflow, it can read a CD, compare it with lender-expected fees, send an exception to title, update the LOS after correction, and notify the closer that the loan is ready to fund. That changes who runs the work. It also raises the stakes for the layers underneath, because an extraction defect can now trigger further action. The real engineering decisions sit in generation 2 and the transition to generation 3, where accuracy, validation, and exception handling determine how much work can proceed unattended.
Why the CD and invoice are the hardest capture problems in the loan file
The CD is a schema problem. Of its 50–60 named line items, some are optional and others apply only in certain cases, and the lender and title versions must agree field by field. Reading an amount is not enough. The extractor must associate it with the correct regulatory fee category, because a plausible number in the wrong cell can still produce a tolerance violation. Vendor invoices add another source of figures that must agree with the closing documents, with errors exposing the lender to investor rejection and TRID audit risk.
These structures also require maintained implementation guidance. MISMO's SMART Doc® 1.02 Implementation Guide reached Final Status in July 2026 with guidance for late charge amounts and broker/loan originator identifiers. That changes the implementation guidance while leaving the underlying SMART Doc v1.02 Specification as it was. The distinction is important when maintaining field mappings and validation rules. A rigid extractor can appear to succeed while quietly assigning data incorrectly, leaving the processor with no reason to question what reaches funding.
What field-level extraction accuracy means for CD and invoice capture specifically
The useful accuracy measure is a named field against a named schema. Character-level OCR accuracy cannot show whether a fee came from the right table cell, and document-level pass/fail does not show which values were wrong. Reading order can defeat otherwise accurate text recognition. For CD and invoice capture, the test is whether each required amount, date, and category was extracted and mapped correctly.
Input quality sets the practical limit before model choice. Native digital PDFs support the highest field accuracy, clean scans at 300+ DPI remain viable, and below-150-DPI scans degrade sharply. Handwritten annotations need to be handled on their own because the assumptions used for typed text do not apply to them. A package containing a machine-readable CD, a handwritten addendum, and a low-resolution invoice therefore needs conditioning before extraction. Sending native PDF pages to text extraction and scans to vision-based OCR also saves the cost and latency of using GPU-backed OCR to read text that is already available.
Accuracy is not uniform across field types, either. Amounts that follow the same format can be easier to extract with confidence than dates that appear in different places. A production policy therefore needs thresholds by field type.
How confidence thresholds and exception routing replace the human stare-and-compare
Confidence turns extraction into an operational decision. In a CD reconciliation workflow, the system extracts a named fee field, assigns a calibrated confidence score, and compares that score with the policy for that field. Values above the threshold pass the confidence gate and go on to validation. Values below the threshold go to exception handling, which keeps them from reaching the LOS as trusted data. The threshold reflects the cost of an error in that field.
The exception must tell someone what needs fixing. For a CD line item, that means identifying the field, the discrepancy value, and the responsible counterparty, such as the title company or settlement agent. A structured exception gives that party enough detail to act, while a generic alert makes them compare the whole document again. When the large majority of documents clear the confidence and validation gates, people can concentrate on the uncertain tail.
That design depends on calibration. Using more than one confidence signal gives a stronger basis for choosing what to review than an average model probability alone. Source traceability is also essential because a vision model can assign high confidence to a value it invented. The receiving reviewer needs a path back to the source pixels.
Validation against known schemas as the layer that catches what extraction misses
Extraction confidence shows how sure the system is that it read the right cell. Schema validation asks whether the captured value satisfies the document's requirements. These are separate tests with different jobs. The system may read a clearly printed amount correctly even when it fails a fee summation, disagrees with another document, or breaks a regulatory tolerance rule. High confidence cannot resolve those contradictions.
For the CD, validation checks fee amounts in each of the tolerance categories, including fees that fall under zero tolerance under TRID. It also checks internal date consistency, including whether the closing date precedes the rate lock, and reconciles lender and title figures within applicable regulatory tolerances. These checks need explicit rules rather than another unconstrained reading of the page. A multi-pass approach checks that the math and dates agree before data moves downstream, catching errors in the numbers when they cost less to fix than at post-close QC.
The appraisal fee on an invoice must match the appraisal fee on the CD, and the title insurance premium must agree with the title invoice. Those comparisons catch mismatches that investor QC would otherwise flag for cure.
The edge cases that break even well-engineered pipelines in production
Clean-document demonstrations leave out some of the hardest mortgage cases. Income documents for a self-employed borrower have uneven structures and more than one schedule type, and their figures must be compared year-over-year. Files with more than one borrower pose a different problem because a field can be read correctly and still belong to the wrong person. Neither defect is solved by recognizing more characters. The pipeline has to preserve the relationship between a value, its document, and the borrower to whom it belongs.
Other edge cases challenge what the page appears to say. A handwritten addendum can override or qualify a typed field, while non-standard tax transcripts vary across IRS form versions and third-party transcript services. Packages with a mix of formats bring these difficulties into one PDF, so each page needs to be routed before extraction. A single processing path is not enough. The system needs validation that recognizes defects in each document type and a confidence floor below which it refuses to pass a value.
Otherwise, partial automation can move the failure downstream. A quiet CD intake error discovered at investor delivery can require a cure letter, a timeline extension, and potential tolerance violation remediation. An output that looks ordinary can be dangerous because no one may question it.
Why building this pipeline in-house compounds in cost faster than most teams anticipate
The initial model is only the beginning of the build. The lasting obligation is maintaining validation rules against changing investor guidelines and agency overlays that do not always agree. Fannie Mae and Freddie Mac count student loan liabilities differently in income qualification, for example. That divergence requires renewed implementation when either agency changes its selling guide. Although the example reaches beyond CD capture, it shows why a mortgage-wide validation layer cannot remain a one-time configuration.
Rocket Close provides a named production reference for the build path. Evaluate the resulting system's field-level guarantees. A benchmark of 90% document-level accuracy across 60 document types does not promise a level of service for each field against a CD schema. That distinction becomes costly when an incorrect fee creates a cure obligation.
Ownership also extends beyond extraction and rules. It includes model and prompt evaluation, document taxonomy changes, exception workflows, LOS integrations, monitoring, security patching, compliance updates, and user support. Buying does not automatically remove these concerns. A platform may miss a lender's document mix or overlays, provide insufficient confidence detail, or leave analysts working in a dashboard separate from the LOS. The sound comparison is between complete operating commitments, including contractual field-level accuracy, rather than a custom build and a vendor's best demonstration.
Data security and compliance requirements that the extraction architecture must satisfy
Mortgage files contain borrower SSNs, income figures, and asset balances, while CDs include property addresses and itemized closing costs. That makes retention a design constraint. Zero data retention is the appropriate default for sensitive document payloads after processing. The extraction architecture has to account for where data goes at every stage.
GDPR Article 25 establishes data protection by design and by default, while SOC 2 Trust Criteria CC6.1 addresses logical access controls protecting information assets from unauthorized access. Those obligations mean a lender looking at AI processing has to review access and data handling as part of the architecture. A verbal vendor assurance is not sufficient for audit. Signed DPA or enterprise agreement terms need to confirm the relevant zero-data-retention commitments and that document payloads are not used for model training.
Agentic workflows make the data path longer. Each tool call moves regulated information through infrastructure, and any hop that writes payloads to logs, caches, or durable queues creates retention that must be disclosed and controlled. A zero-retention model endpoint does not settle what happens elsewhere in that path. Compliance architecture belongs in the extraction tool selection criteria before deployment.
What a production-grade CD and invoice capture pipeline looks like end to end
A lender evaluating its stack can test for six connected layers. The first is document conditioning, which assesses, sorts, and splits packages before routing native pages to text extraction and scans to vision OCR. The second is field-level extraction against named CD fee categories and invoice line items, with confidence that can be traced back to the source content. The third is schema validation of summations, tolerance categories, dates, and cross-document agreement. Each layer has a distinct acceptance test.
The fourth layer is structured exception routing. It identifies the line item, discrepancy, and responsible counterparty so that uncertain data produces an actionable request. The fifth pairs LOS write-back with a tamper-proof audit trail that records the extracted values, confidence scores, and validation results. Only validated structured data belongs in that write-back path. Together, these layers make the decision to pass or stop a field inspectable.
The sixth, agentic layer acts on those outputs. It compares CD data with expected fees, triggers exception emails, updates the LOS after correction, and notifies the closer. It does not replace the controls beneath it. The final purchasing test is whether the supplier commits contractually to field-level accuracy against the named schema, because a production obligation is different from a demo claim.